The integration of voice communication and AI represents a big step forward in human-machine interaction that can potentially transform traditional methods of communication. For instance, in the context of a phone call, you no longer need another human to be present on the other end of the line. Instead, people can engage in natural, conversational interactions with AI systems. As this technology continues to evolve, the potential for voice-enabled AI applications also continues to grow, ranging from customer service bots to personal assistants and beyond.
This tutorial explains how to implement a voice call bot that enables conversations with ChatGPT over the phone. In particular, you'll use Twilio for telecommunication services, AssemblyAI for Speech-to-Text transcription, and AssemblyAI Text-to-Speech to speak ChatGPT's answers back to the caller.
Implementing a Voice Call Bot
In this tutorial, you'll implement a voice call bot using several technologies. Below is a brief overview of each technology and its role in the implementation:
- Twilio is a cloud communications platform that enables developers to add communication features to their applications through its API. Twilio allows the application to make and receive phone calls, records what the caller says, and plays audio back to them.
- AssemblyAI provides Voice AI technology that can transcribe audio to text with high accuracy. AssemblyAI will transcribe human speech from the phone call into text, which can then be used as input for ChatGPT to understand and respond to users. AssemblyAI Text-to-Speech (TTS) then converts ChatGPT's text responses into audible speech that the caller can hear.
- GPT-4 is an advanced Generative Pretrained Transformer (GPT) model developed by OpenAI. GPT-4 will act as the brain behind the application, processing the transcribed text from AssemblyAI and formulating responses.
- Node.js is a JavaScript runtime. It allows you to build scalable network applications and will be used to create the backend server for handling calls and processing data.
- npm (Node Package Manager) is the default package manager for Node.js. It helps you manage and install dependencies required for your Node.js applications, including libraries for handling Twilio API, HTTP requests, and other necessary functionalities.
Twilio will receive the voice of a speaker and use TwiML instructions to forward this audio to your application. Your application will then send the audio to AssemblyAI, which transcribes the recording to text. The transcription is then sent to GPT-4 to generate a text response. Finally, AssemblyAI Text-to-Speech converts the response into phone-ready audio, which Twilio plays to the user over the phone.
Caller ──speech──▶ Twilio (TwiML <Record>) ──recording──▶ AssemblyAI Speech-to-Text
                                                                │ transcript
                                                                ▼
Caller ◀──audio── Twilio (TwiML <Play>) ◀──μ-law WAV── AssemblyAI Text-to-Speech ◀──text── GPT-4
Setting Up the Development Environment
Before implementing the voice call bot, you need to set up the development environment. This involves installing Node.js and npm, setting up the project, and installing essential libraries and services for Twilio, OpenAI, and AssemblyAI.
Set Up Node.js and npm
Node.js is a runtime environment that allows you to run JavaScript on the server. npm is a package manager that comes bundled with Node.js and helps to manage the packages that the project requires.
To install Node.js and npm, visit the official Node.js website and download the installer for your operating system.
After the installation, open your terminal and type node -v and npm -v. This will verify that both Node.js and npm were successfully installed. You should see the version numbers of Node.js and npm displayed, confirming that they are ready for use. This tutorial uses the latest version of Node.js and npm. Ensure you have these installed on your system to follow along. You can download the latest LTS version of Node.js from the official website.
You also need to initialize a new Node.js project. Create a main folder for your project (voice-call-bot, for instance). Navigate to this folder and open a terminal. In the terminal, run the following command:
npm init -yOpen package.json and add "type": "module" to use ES modules.
Install Additional Libraries
Next, install some additional SDKs. The Twilio SDK is needed to interact with Twilio's APIs from the Node.js application. To respond to incoming calls, you'll need to set up an Express server. The AssemblyAI SDK provides both Speech-to-Text and Text-to-Speech, and the OpenAI SDK lets you use ChatGPT to generate responses. Text-to-Speech needs version 4.42.0 or later of the assemblyai package, which a fresh install gives you.
Navigate to your Node.js project's directory, open a terminal, and run this command to install all required libraries in one go:
npm install twilio express openai assemblyai --saveInitialize a Twilio Project
A Twilio account is required for this tutorial. If you are new to Twilio, you'll need to sign up for a trial Twilio account to access the APIs and services (like making and receiving calls) that will enable the voice call bot to communicate over the phone.
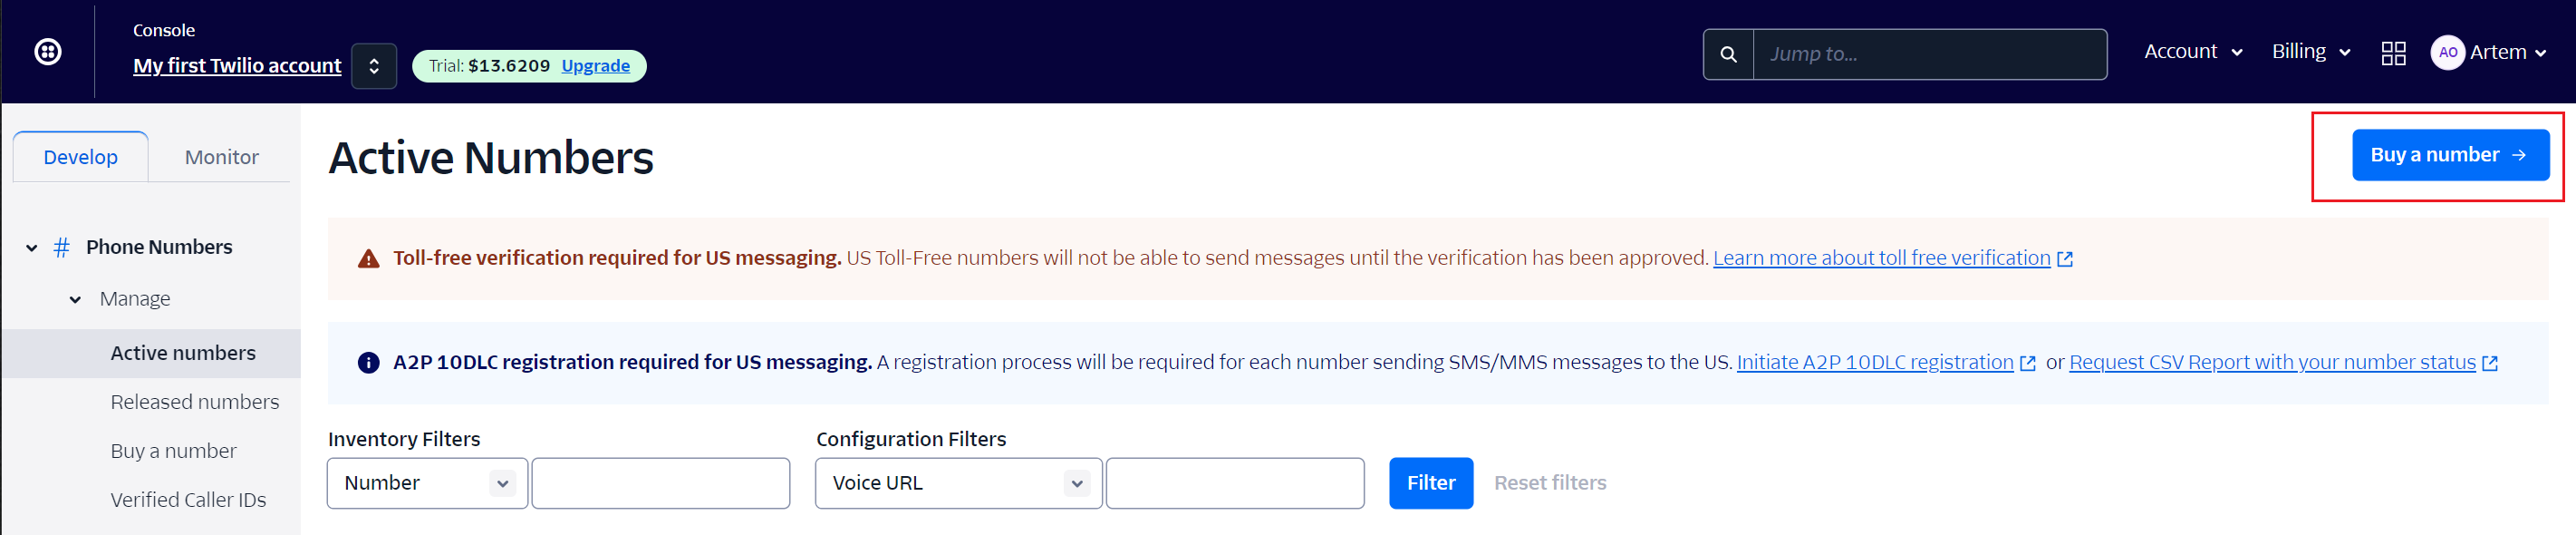
You'll also need a Twilio phone number to make and receive calls. Once you've registered for Twilio, you can use the trial budget of your Twilio account to purchase a phone number. To do so, open the Twilio console, then navigate to Phone Numbers > Manage > Active numbers > Buy a number:
Obtain Twilio Credentials
To obtain your Twilio Account Sid and Auth Token, you'll need to sign up for or log into your account at the Twilio website. Once logged in, navigate to the Twilio Console Dashboard. Your Account SID is displayed prominently on the dashboard, and the Auth Token can be revealed by clicking the Show link in the API Credentials section.
Install ngrok
You'll also need to install ngrok, which you'll use to create a secure tunnel to your localhost. Twilio uses webhooks to communicate events, like incoming calls, to your application. ngrok allows you to expose your local development environment to the internet, making it possible for Twilio to send webhook requests directly to the application running on your local machine.
Sign up for a free ngrok account, then download the executable for your operating system and follow the instructions to install it.
Set Up AssemblyAI
AssemblyAI's API will transcribe the audio received from Twilio voice calls into text, which can then be used to generate responses through ChatGPT. AssemblyAI Text-to-Speech then speaks those responses to the caller, and both run on the same API key.
AssemblyAI-TTS-1, the model behind AssemblyAI Text-to-Speech, is built for conversational voice agents and trained on millions of hours of audio, including real conversational data. It delivers frontier-level quality, runs faster than other production voice agent TTS models, and has unlimited concurrency. Pricing is $15 per 1M characters, billed on input characters; see pricing for current rates.
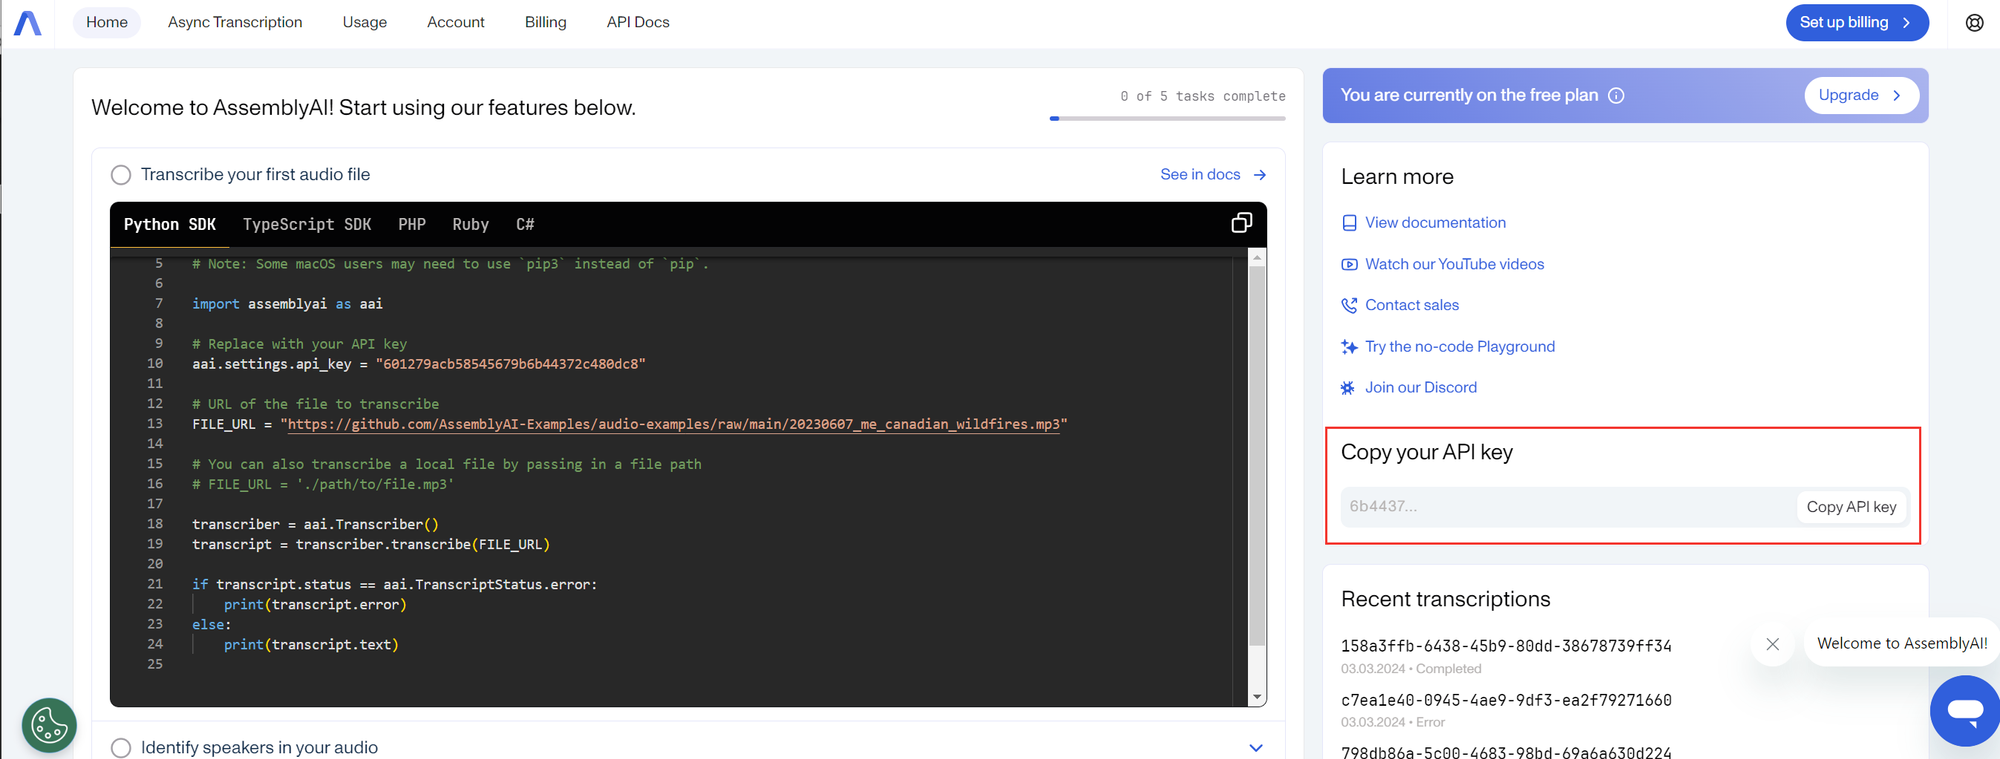
Register for AssemblyAI if you don't already have an account. Once you're logged in, you can find your API key in the dashboard; you'll need this to authenticate requests to the AssemblyAI APIs.
Set Up OpenAI
Connecting your voice call bot to GPT-4 enables it to understand and generate human-like responses based on the transcribed text from AssemblyAI. You'll need an API key from OpenAI, which is required to authenticate your requests to GPT-4. If you haven't already signed up, go ahead and create an OpenAI account. Once you're logged in, the API key can be created on the OpenAI platform.
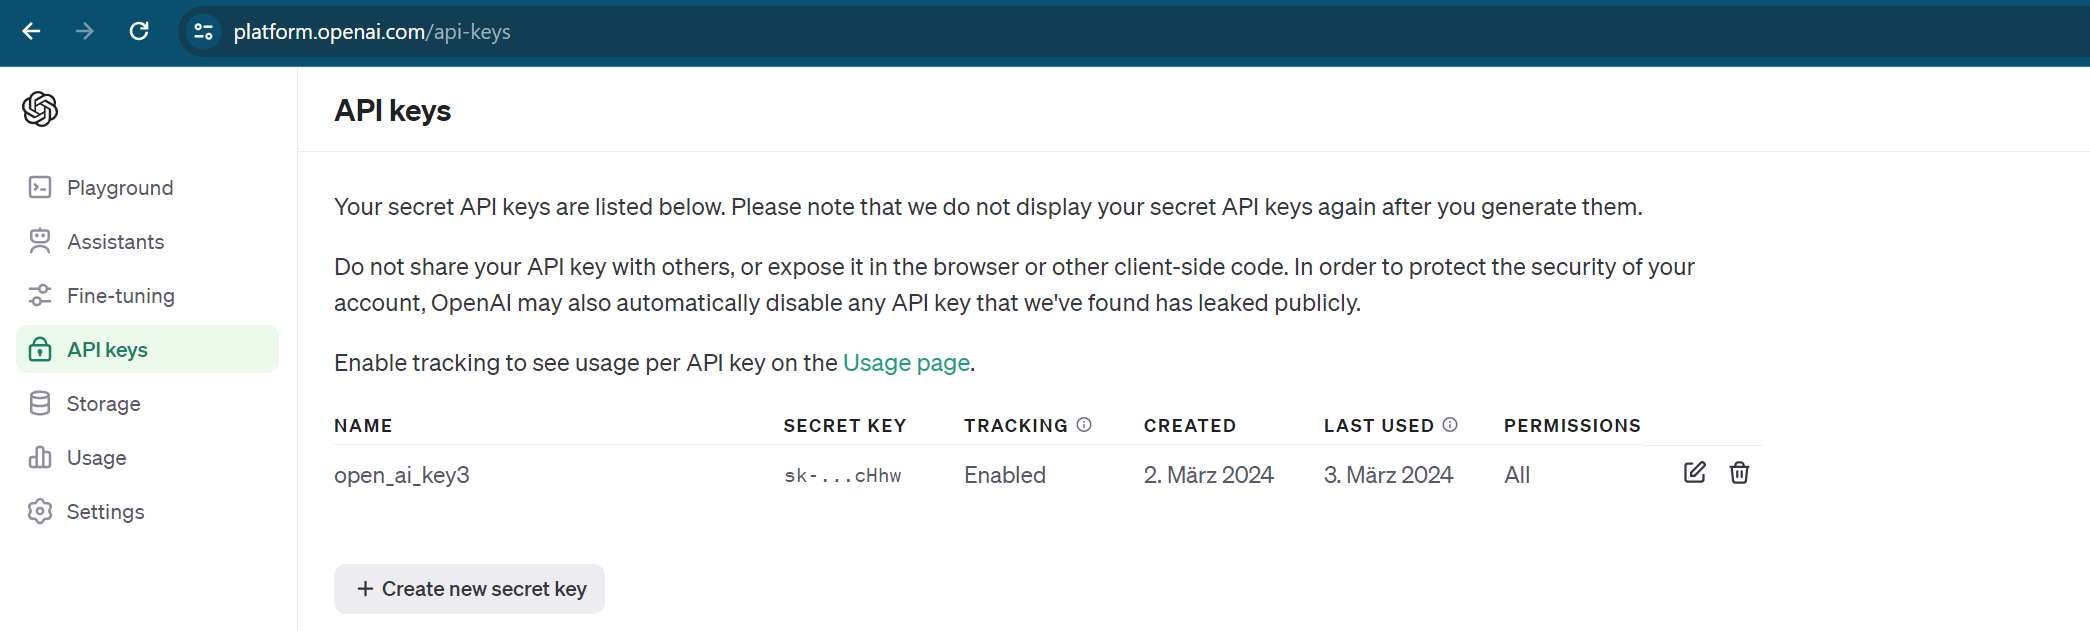
Manage API Keys
You need to ensure that you manage API keys securely to prevent unauthorized access and potential security vulnerabilities. Instead of embedding API keys directly in the code, a good practice is to store them in environment variables. You can do this in a Node.js project using a .env file. First, install the dotenv package in your Node.js project to load environment variables:
npm install dotenv --saveNext, create a .env file in the directory of your project and add your API keys there, like so:
OPENAI_API_KEY=<YOUR_OPENAI_API_KEY>
ASSEMBLYAI_API_KEY=<YOUR_ASSEMBLYAI_API_KEY>
TWILIO_ACCOUNT_SID=<YOUR_TWILIO_ACCOUNT_SID>
TWILIO_AUTH_TOKEN=<YOUR_TWILIO_AUTH_TOKEN>
Import the required libraries and initialize variables
In your project, create a new file (such as index.js). You need to set up the application with external services and libraries, including Twilio for voice communication, OpenAI for accessing AI models, and AssemblyAI for audio transcription.
Paste the following code into the index.js file to import all the necessary libraries:
import express from "express";
import twilio from "twilio";
import OpenAI from "openai";
import { AssemblyAI } from "assemblyai";
import { randomUUID } from "node:crypto";
// Load environment variables from .env file
import "dotenv/config";

const { VoiceResponse } = twilio.twiml;

const app = express();

app.use(express.urlencoded({ extended: false }));

const openAiClient = new OpenAI({ apiKey: process.env.OPENAI_API_KEY });
const assemblyAiClient = new AssemblyAI({
  apiKey: process.env.ASSEMBLYAI_API_KEY,
});
const twilioClient = twilio(
  process.env.TWILIO_ACCOUNT_SID,
  process.env.TWILIO_AUTH_TOKEN
);

const chatHistories = {};
This code imports the express, twilio, openai, and assemblyai libraries. It also creates an Express application instance with const app = express();, which can define routes, middleware, and server settings. The line app.use(express.urlencoded({ extended: false })); tells the Express application to parse URL-encoded bodies, which is how Twilio sends its webhook data. The VoiceResponse component builds TwiML responses for handling voice calls.
Furthermore, the code creates the OpenAI, AssemblyAI, and Twilio clients from the keys in your .env file. The same AssemblyAI client handles both Speech-to-Text and Text-to-Speech. randomUUID names the audio clips you'll create in the Text-to-Speech step.
'chatHistories' stores the chat histories keyed by a unique identifier (eg, a call SID provided by Twilio). In a production application, you would store this in a datastore, but for the sake of this demo, you'll store it in memory.
Start ngrok
Open a new terminal and start ngrok to create a secure tunnel to the port of the application (eg 4000 if your application will run on port 4000). Then, run the following command in the terminal:
ngrok http 4000Copy the ngrok HTTPS URL
After starting ngrok, it will display several lines of output in the terminal. Look for the line that begins with "Forwarding" and copy the HTTPS URL. This URL is the public address that ngrok created for your local server.
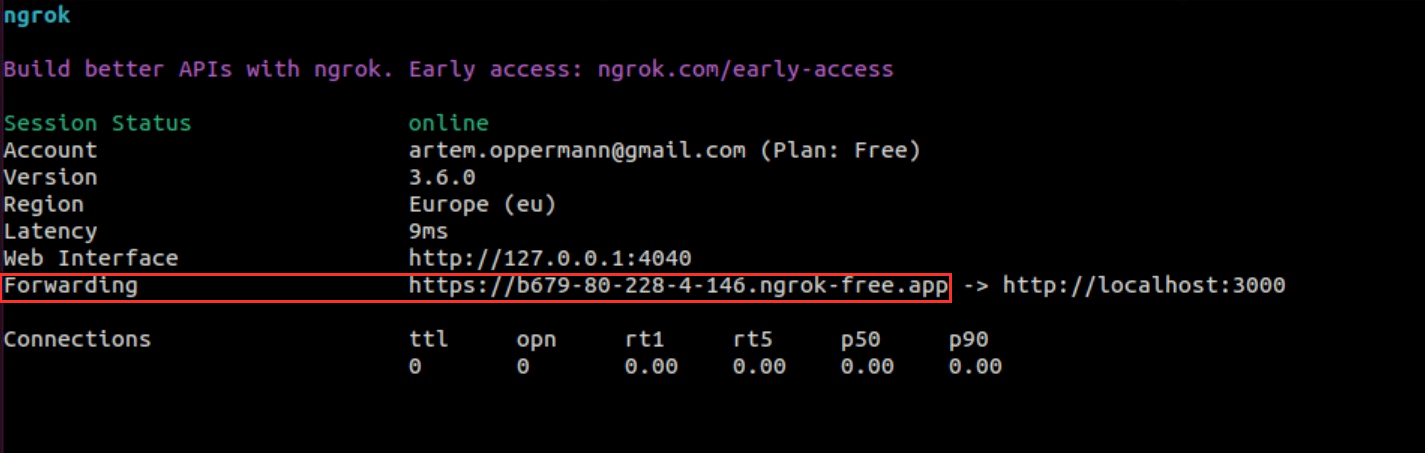
In index.js, add the ngrok URL that will be used later in the code:
const PUBLIC_URL = "<YOUR_NGROK_URL>";Configure Twilio Webhook
Next, configure your Twilio webhook to set up Twilio to forward incoming voice calls to your application while enabling it to handle these calls according to your defined logic. To configure the webhook, log in to your Twilio account and navigate to the console. Go to Phone Numbers > Manage > Active numbers and select the phone number you're using for the voice call bot. In the phone number configuration, find the Voice Configuration section. Paste the ngrok HTTPS URL you copied into the A call comes in webhook URL field, followed by the endpoint your application uses to handle calls (eg https://yoursubdomain.ngrok.io/voice if the application expects incoming calls at the /voice endpoint).
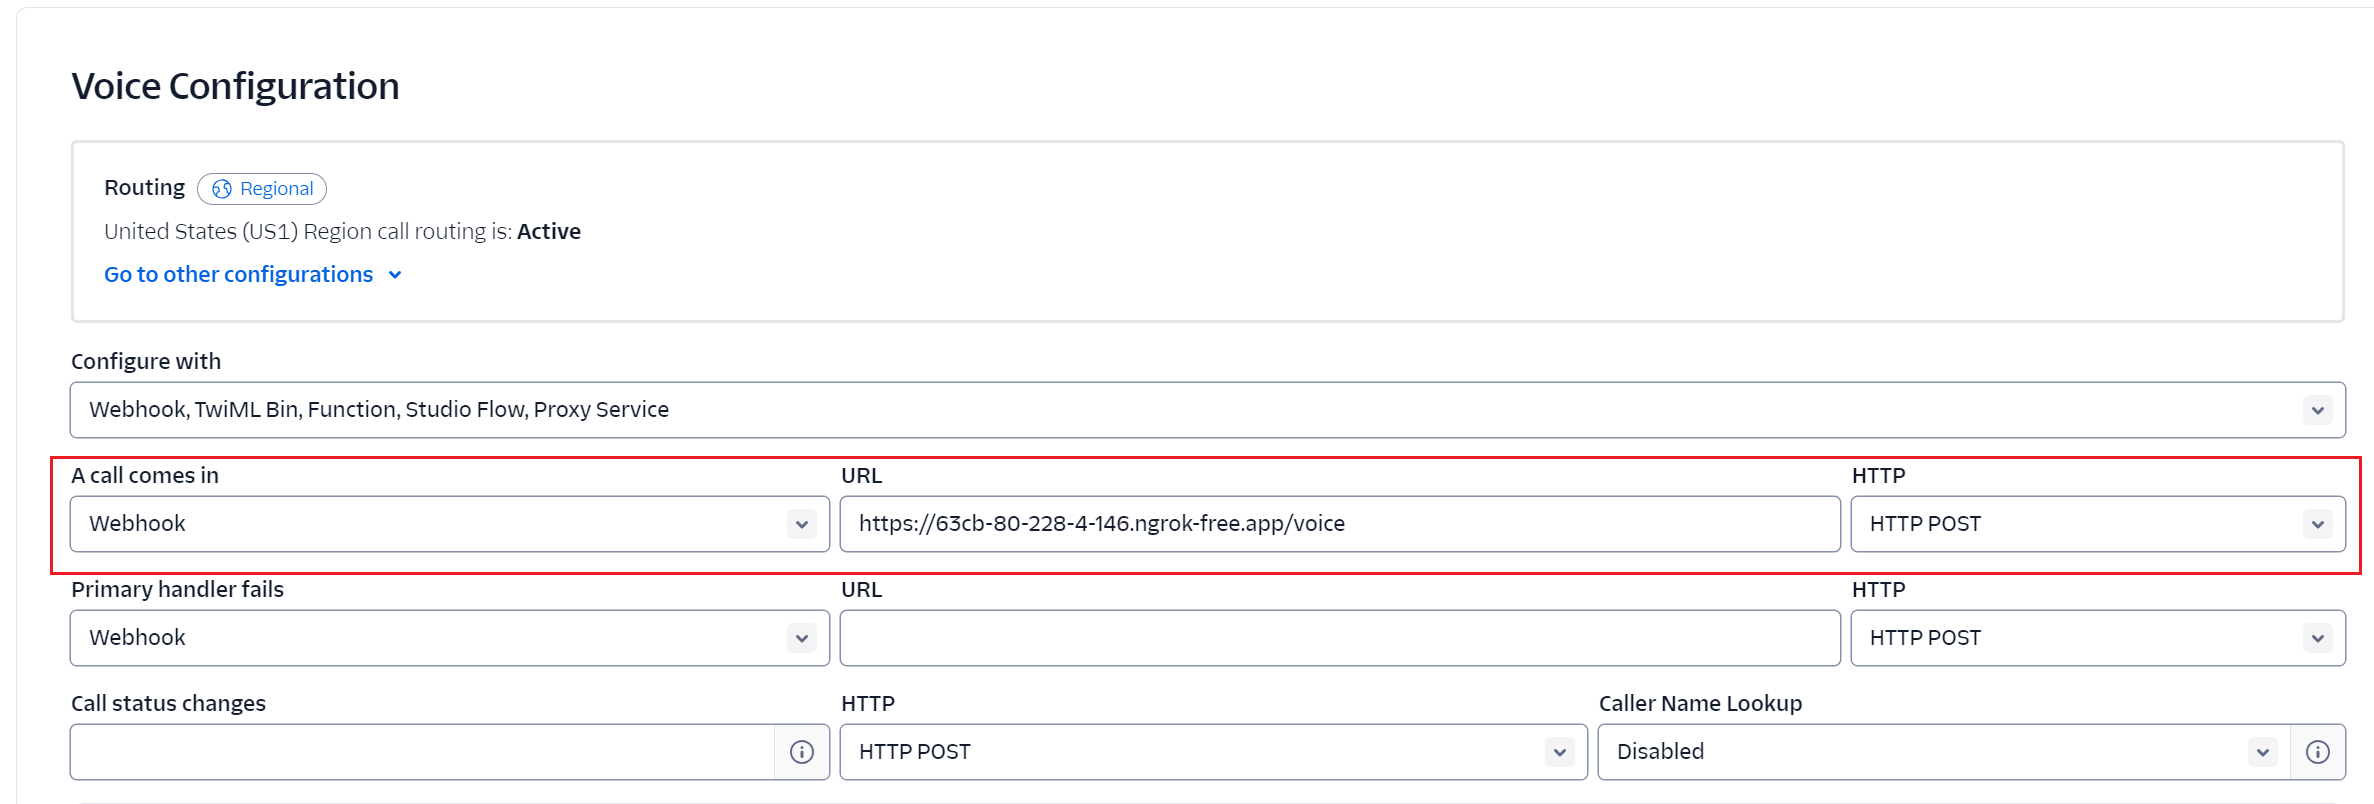
Add AssemblyAI Text-to-Speech
Every time the bot talks, whether it's the greeting or ChatGPT's answer, it needs audio that a phone line can play. The phone network carries 8 kHz G.711 μ-law audio, so the app asks AssemblyAI Text-to-Speech for exactly that: encoding: "pcm_mulaw" and sample_rate: 8000. The model's native output is 24 kHz 16-bit PCM, and the server resamples and encodes it before sending, so there's no audio conversion on your side. With container: "wav", the audio comes back as a WAV file whose header tells Twilio what format it's in.
Add the following code to index.js. The speak function synthesizes a piece of text, keeps the WAV bytes in memory, and returns a URL under your ngrok address that Twilio can fetch with a TwiML <Play> instruction:
const VOICE_ID = "49c443a4-8a1d-5f7e-b70b-98bdbd9823c3"; // Audrey

// The fixed lines the bot says on every call
const PROMPTS = {
  greeting: "Please say something after the beep, and I will transcribe it.",
  hold: "Processing your request, please hold.",
  menu: "Press 1 to speak again, or any other key to end the call.",
  goodbye: "Thank you for using our service. Goodbye!",
};

const audioClips = new Map(); // clip id -> WAV bytes
const promptClips = new Map(); // prompt text -> clip id

// Synthesize text with AssemblyAI TTS and return a URL Twilio can <Play>
async function speak(text, { cache = false } = {}) {
  let id = cache ? promptClips.get(text) : undefined;
  if (!id) {
    const { audio } = await assemblyAiClient.tts.synthesize({
      text,
      voice_id: VOICE_ID,
      language: "english",
      encoding: "pcm_mulaw", // 8-bit G.711 mu-law, the phone network's codec
      sample_rate: 8000,
      container: "wav",
    });
    id = randomUUID();
    audioClips.set(id, Buffer.from(audio));
    if (cache) {
      promptClips.set(text, id);
    } else {
      // A reply is played once, so drop it after ten minutes
      setTimeout(() => audioClips.delete(id), 10 * 60 * 1000);
    }
  }
  return `${PUBLIC_URL}/audio/${id}`;
}

// Twilio fetches each clip from this route
app.get("/audio/:id", (req, res) => {
  const clip = audioClips.get(req.params.id);
  if (!clip) {
    res.status(404).end();
    return;
  }
  res.type("audio/wav").send(clip);
});
assemblyAiClient.tts.synthesize sends the text to the Text-to-Speech HTTP API and returns the complete audio in audio. The voice is set explicitly with voice_id; this example uses Audrey, and you can pick another from the voice library. One request takes up to 5,000 characters, which is plenty for a spoken GPT-4 answer.
The four fixed prompts are synthesized once and cached by their text (cache: true), so callers never wait for them. GPT-4's replies are new every time, so each one is synthesized when it's ready and deleted from memory after ten minutes. The /audio/:id route serves the clips to Twilio as audio/wav.
This record-then-reply design keeps the tutorial simple. For a real-time agent that streams audio both ways over Twilio Media Streams and lets callers interrupt, see this Twilio phone agent tutorial, which uses the same 8 kHz μ-law format over a Text-to-Speech WebSocket session. The Text-to-Speech quickstart covers both interfaces.
Integrate Twilio for Voice Calls and Text-to-Speech
Next, you'll define a route in the application to handle incoming voice calls via a POST request to the /voice endpoint. The app uses Twilio's VoiceResponse class to control the call flow and plays AssemblyAI Text-to-Speech audio to give instructions to the caller.
Paste the code below into the index.js file to define the route:
// Define the route for incoming voice calls
app.post("/voice", async (req, res) => {
  const callSid = req.body.CallSid;
  // Keep the history when the caller presses 1 to speak again
  chatHistories[callSid] ??= [];

  const twiml = new VoiceResponse();
  twiml.play(await speak(PROMPTS.greeting, { cache: true }));

  // Record the caller's speech and send the recording to a webhook endpoint for processing
  twiml.record({
    timeout: 5,
    transcribe: false, // Use AssemblyAI for transcription
    action: "/recording-done",
    recordingStatusCallback: "/recording", // Specify the route to handle the recording
    recordingStatusCallbackEvent: ["completed"],
    recordingStatusCallbackMethod: "POST",
  });

  res.writeHead(200, { "Content-Type": "text/xml" });
  res.end(twiml.toString());
});
When a caller reaches this endpoint, the code creates an empty array in the chatHistories object if there isn't one yet, using callSid from the request body as the key to track the chat history of a specific phone call session. Because ??= only assigns when the key is missing, the history survives when the caller presses 1 to ask another question. Then, a new instance of VoiceResponse is created. This object is used to generate TwiML. The twiml.play method instructs Twilio to play the greeting, which speak synthesized with AssemblyAI Text-to-Speech. In this case, the message is "Please say something after the beep, and I will transcribe it." This guides the caller on what to do next. The twiml.record method configures Twilio to record the caller's speech. The following options are passed to record:
timeout: 5means the recording will end if there is silence for 5 seconds.transcribe: falseindicates that Twilio's automatic transcription is not used. The intention here is to use AssemblyAI for transcription instead.action: '/recording-done'specifies the route that Twilio should request once the recording is complete. This route will be responsible for sending a response to the caller while the recording is being processed. Note that although this route is called after the recording is complete, the recording file may not yet be available. That’s why therecordingStatusCallbackparameter is used for a more accurate callback.recordingStatusCallback: '/recording',recordingStatusCallbackEvent: ['completed'], andrecordingStatusCallbackMethod: 'POST'specifies the route that will be requested after the recording is completed and the recording file is available. This route will start the processing.
Integrate AssemblyAI for Speech-to-Text
You'll now implement a new route (/recording) in the application to handle the callback from Twilio after a voice recording is complete. In this route, you'll manage the process of converting voice calls to text. While the actual implementation of the GPT-4 connection is covered later, you'll first set up the foundation for later interaction with ChatGPT to generate responses based on the transcribed text, then address how to handle these responses.
Copy the code snippet below and paste it into the existing index.js file:
app.post("/recording", (req, res) => {
  const callSid = req.body.CallSid;
  const recordingUrl = req.body.RecordingUrl;
  res.status(200).end();

  // Start asynchronous processing
  processRecording(callSid, recordingUrl);
});

app.post("/recording-done", async (req, res) => {
  const twiml = new VoiceResponse();
  twiml.play(await speak(PROMPTS.hold, { cache: true }));
  twiml.redirect("/enqueue");
  res.writeHead(200, { "Content-Type": "text/xml" });
  res.end(twiml.toString());
});

app.post("/wait", (req, res) => {
  const twiml = new VoiceResponse();
  twiml.pause({ length: 1 });
  res.writeHead(200, { "Content-Type": "text/xml" });
  res.end(twiml.toString());
});

app.post("/enqueue", (req, res) => {
  const twiml = new VoiceResponse();
  twiml.enqueue(
    {
      waitUrl: "/wait",
    },
    "wait-for-assistant-queue"
  );
  res.writeHead(200, { "Content-Type": "text/xml" });
  res.end(twiml.toString());
});

async function processRecording(callSid, recordingUrl) {
  const params = { audio: recordingUrl + ".mp3" };

  try {
    const transcript = await assemblyAiClient.transcripts.transcribe(params);
    if (transcript.status === "error") {
      throw new Error(transcript.error);
    }
    const gpt4Response = await generateResponse(transcript.text, callSid);

    // Speak GPT-4's answer with AssemblyAI TTS, then offer the menu
    const twiml = new VoiceResponse();
    twiml.play(await speak(gpt4Response));
    twiml.play(await speak(PROMPTS.menu, { cache: true }));
    twiml.gather({
      numDigits: 1,
      action: PUBLIC_URL + "/followup",
      method: "POST",
    });

    // Redirect to update the call with new instructions
    await twilioClient.calls(callSid).update({ twiml: twiml.toString() });
  } catch (error) {
    console.error("Failed to process recording", error);
  }
}

app.post("/followup", async (req, res) => {
  const twiml = new VoiceResponse();
  if (req.body.Digits === "1") {
    twiml.redirect("/voice");
  } else {
    twiml.play(await speak(PROMPTS.goodbye, { cache: true }));
    twiml.hangup();
  }

  res.writeHead(200, { "Content-Type": "text/xml" });
  res.end(twiml.toString());
});
The recording route extracts the URL of the voice recording from the request body sent by Twilio, which contains the audio file of the recorded call. It then calls the processRecording function to asynchronously process the recording.
The /recording-done endpoint redirects the call to the /enqueue route, which queues the call using the /wait route. The /wait route simply pauses the call for 1 second. This route is repeatedly called by the enqueue verb, which keeps the call connected while the processRecording function finishes.
The processRecording function uses the AssemblyAI client to request the audio transcription. The transcribe method sends the recording URL to AssemblyAI for transcription by passing it as a parameter. AssemblyAI processes the audio and returns the transcription text; if the transcription fails, the error is logged. The transcribed text is then sent to the function generateResponse (described in the next section), which queries GPT-4 to generate a relevant response based on the transcription. Following that, speak turns the response generated by GPT-4 into μ-law audio with AssemblyAI Text-to-Speech, and Twilio's VoiceResponse is used to create a TwiML response with a <Play> instruction that plays it back to the caller. The "please hold" and goodbye prompts are played the same way.
After delivering the response, the application uses Twilio's gather method to ask the user to press '1' to continue the conversation or any other key to end the call. This input is then processed in the /followup endpoint. If the user presses '1', the application restarts the interaction by redirecting to the /voice endpoint. If any other key is pressed, the application thanks the user and ends the call with the hangup() method.
By default, Twilio’s call recordings are protected by HTTP basic authentication, which may prevent AssemblyAI from accessing them. Turn the HTTP basic authentication off by going to Voice > Settings > General from the Twilio dashboard and selecting "Disabled" under "HTTP Basic Authentication for media access."
Prompt GPT-4
You'll now implement a function to interact with the OpenAI GPT-4 model via the OpenAI API to send text to GPT-4 and receive a generated text response based on the provided input. Extend the index.js file with the code below:
async function generateResponse(text, callSid) {
  const messages = chatHistories[callSid].map((msg) => ({
    role: msg.role,
    content: msg.content,
  }));
  messages.push({ role: "user", content: text });

  try {
    const completion = await openAiClient.chat.completions.create({
      model: "gpt-4",
      messages: messages,
    });
    const response = completion.choices[0].message.content;
    chatHistories[callSid].push({ role: "user", content: text });
    chatHistories[callSid].push({ role: "assistant", content: response });
    return response;
  } catch (error) {
    console.error("Error querying GPT-4", error);
    return "I'm sorry, but I couldn't process your request.";
  }
}
This function initializes the OpenAI SDK with an API key, allowing the application to authenticate and interact with OpenAI's services. After that, it makes an asynchronous call to the openai.chat.completions.create method. This method sends a request to the OpenAI API, asking the AI to produce a response that is contextually aligned with the input, effectively generating a coherent and contextually relevant text completion. The method takes an object as an argument, specifying the model ("gpt-4") and an array of messages. Each message is an object containing a role (set to "user" for this request) and the content, which is the text provided as an argument to the generateResponse function. This text represents the caller's transcribed voice message. If the API call is successful, the function extracts the first completion message from the response (completion.choices[0].message.content) and returns it. This is the generated text based on the input provided to the GPT-4 model.
Furthermore, the function utilizes the chatHistories object to maintain a contextual conversation history for each unique call session identified by a callSid. Within this function, each new user input and the subsequent AI response to the session's history is appended to the history object chatHistories. The entire conversation history stored in the chatHistories object for the current session is retrieved and sent as a sequence of messages to the GPT-4 model. This process ensures that GPT-4 has the full context of the conversation, allowing it to generate more relevant and coherent responses that are consistent with the prior dialogue.
Starting the Server
You can now finish the setup of the application by extending the index.js file with the functionality to start the server. To allow the application to listen for incoming requests on a specified port, copy and paste the code below into the end of the index.js file:
const PORT = 4000;

// Start the Express server
app.listen(PORT, async () => {
  console.log(`Server running on port ${PORT}`);
  // Synthesize the fixed prompts once, so no caller waits for them
  await Promise.all(
    Object.values(PROMPTS).map((text) => speak(text, { cache: true }))
  );
  console.log("Prompts ready");
});
This code instructs the application to start listening to the port defined by the PORT variable, which is set to 4000. This makes the application ready to accept incoming HTTP requests on this port. While this example uses port 4000, you can adjust the PORT variable to accommodate different environments or requirements. Once the server is listening, it synthesizes the fixed prompts with AssemblyAI Text-to-Speech and logs Prompts ready.
Testing the Application
To test your voice call bot, you need to create a secure tunnel to your local server so Twilio can interact with the application running on your local machine. You can do this by following the steps below.
Start Your Node.js Application
First, ensure your voice call bot application is running locally. Open a terminal in the directory of the Node.js project and start the application by running the following command:
node index.jsTest the Application
You're finally ready to test your voice call bot. Use a phone to call the Twilio phone number you configured. Your call will be routed through Twilio to your local server via the ngrok tunnel. You can speak to the voice call bot by asking it a question. If the application works, you'll hear the answer to this question over your phone, spoken by AssemblyAI Text-to-Speech.
Conclusion
In this tutorial, you learned how to create a voice call bot using Twilio for voice communication, AssemblyAI for speech-to-text transcription and text-to-speech, and OpenAI's GPT-4 for generating human-like text responses. In particular, you saw how these technologies can be integrated to build an application that can interact with users through voice calls, understand their spoken queries, and respond in a conversational manner. This tutorial could be an entry point for building more advanced applications for human-machine interactions, ranging from customer service to interactive voice surveys.
AssemblyAI builds AI models that transcribe and understand human speech and, with AssemblyAI Text-to-Speech, give voice agents a voice of their own. Developers can convert speech to text in real time and speak responses back on the same account, which makes it possible to create applications that interact with users in a natural and intuitive way. If you're interested in exploring AssemblyAI and how it can be integrated, check out the official AssemblyAI docs for more information.
Frequently Asked Questions (FAQs)
Can Twilio play a μ-law WAV file with the Play verb?
Yes. Twilio’s <Play> reference lists audio/wav, audio/wave and audio/x-wav among the MIME types it fetches, along with audio/mpeg and audio/ulaw. This tutorial serves an 8 kHz, mono, G.711 μ-law WAV file with an audio/wav Content-Type, which is the phone network’s own codec, so there’s no high-bitrate MP3 for Twilio to transcode first.
Why request 8 kHz μ-law audio instead of the default format?
AssemblyAI Text-to-Speech natively outputs 24 kHz 16-bit PCM, but a phone call carries 8 kHz G.711 audio. Setting encoding to pcm_mulaw and sample_rate to 8000 makes the server resample and encode the audio once, so the file is already phone-ready when Twilio fetches it. With container set to wav, the response carries a WAV header with format code 7 (mu-law) that describes those bytes.
How long can a spoken GPT-4 reply be?
One Text-to-Speech HTTP request accepts up to 5,000 characters, which covers a typical spoken answer. For longer replies, split the text into sentences or paragraphs and synthesize each piece, then add one <Play> instruction per clip.
How much does AssemblyAI Text-to-Speech cost?
AssemblyAI Text-to-Speech costs $15 per 1M characters, billed on input characters. The same API key covers Speech-to-Text and Text-to-Speech; see the pricing page for current rates.
Which voices and languages can the phone bot use?
The voice catalog in the AssemblyAI dashboard holds thousands of voices across six languages: English, Spanish, German, Italian, Portuguese and French. Change VOICE_ID to any voice_id from the voice library, and set language to the language of the text you send.
Can callers interrupt the bot while it’s talking?
Not in this record-then-reply design, because Twilio plays each clip to the end before it records again. For a real-time phone agent that streams audio both ways and handles interruptions, use Twilio Media Streams as shown in the Twilio phone agent tutorial.