Note: This blog post is part 3 of a 3-part series. See OpenAI Whisper for Developers: Choosing Between API, Local, or Server-Side Transcription for the first in the series and How to use Whisper API to transcribe audio in JavaScript for the second.
Let's explore how to run Whisper directly in the browser. This approach offers several compelling advantages over API-based solutions: complete offline functionality eliminates network dependencies and enables transcription in environments without internet connectivity, enhanced privacy ensures that sensitive audio data never leaves the user's device, and cost elimination removes per-request charges that can accumulate with high-volume usage.
Browser-based Whisper implementations leverage WebAssembly (WASM) technology to run machine learning models natively in the browser. WebAssembly is a binary instruction format that enables near-native performance for computationally intensive tasks like neural network inference. For Whisper, this means we can run the same transformer architecture that powers the original Python implementation directly in JavaScript, albeit with some performance trade-offs compared to GPU-accelerated server environments.
The implementation we'll use comes from Hugging Face's [Transformers.js] library, which provides JavaScript bindings for popular transformer models. This library handles the complexities of model loading, WebAssembly compilation, and tensor operations, presenting a clean API similar to the Python transformers library.
To get started with browser-based Whisper, install the Transformers.js library:
Create a new file src/client/whisperClient.js to encapsulate all browser-based Whisper functionality:
This code defines a WhisperClient class that handles loading the Whisper model through a Transformations pipeline. The load method initializes the model and provides a callback for tracking loading progress. We also added a isLoaded and isLoading flags to prevent multiple concurrent loads.
The chunked processing approach (chunk_length_s: 30 with stride_length_s: 5) handles longer audio files by processing them in overlapping segments. This prevents memory issues with large files while maintaining transcription continuity through the 5-second overlap between chunks.
Update your HTML to include transcription method selection. Add this section right after your main heading:
This allows users to choose between the OpenAI API and the browser-based Whisper implementation. Now let's write the code to load the Whisper model when the "browser" option is selected. Update the src/client/index.js file with the following code:
First, we set an "on change" event listener on the transcription method selection. If the user selects the "browser" option, we check if the Whisper model is already loaded or if it's currently loading. If not, we call the WhisperClient.load function to load the model. Most of the code above is handling the visual feedback for model loading:
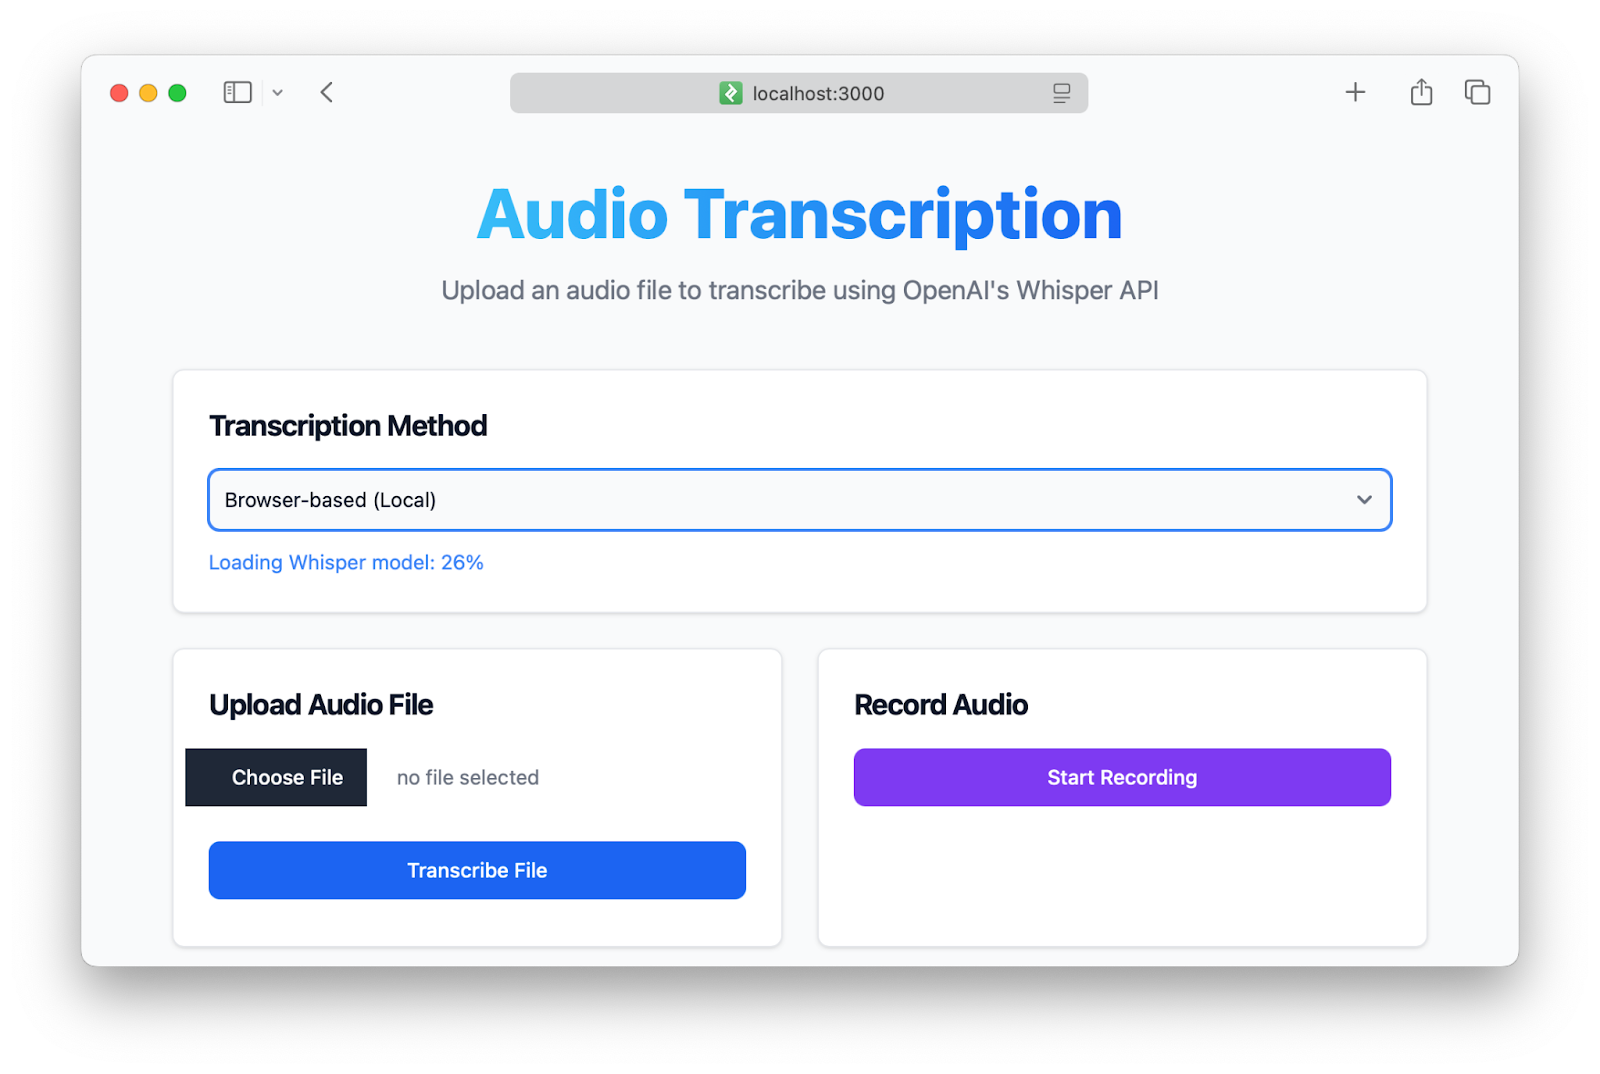
Once the model is loaded, we update the status message to indicate that the Whisper model is ready for use. At this point, we can implement the transcription functionality using the WhisperClient class. Let's implement the BrowserWhisperTranscriber transcriber which extends the base Transcriber class and prepares the audio data for transcription:
This implementation handles the audio processing pipeline required for browser-based Whisper transcription. The audio decoding process uses the Web Audio API to convert various audio formats into the raw PCM data that Whisper expects. This involves several steps:
Format Normalization: The decodeAudioBuffer method handles the conversion from various audio formats (MP3, WAV, WebM, etc.) into standardized PCM audio data. The Web Audio API automatically handles most format complexities, but we need to ensure the output matches Whisper's requirements.
Sample Rate Conversion: Whisper models are trained on 16kHz audio, so any input audio must be resampled to this rate. The resampleAudio method implements linear interpolation resampling, which provides good quality for speech audio while being computationally efficient for browser environments.
Channel Reduction: Whisper expects mono (single-channel) audio, so stereo recordings are converted by taking the first channel. For applications requiring better stereo handling, you could implement channel mixing instead.
With all components in place, rebuild your application and test both transcription methods:
Navigate to http://localhost:8000 and test the browser-based functionality:
- Select "Browser Whisper (Local)" from the transcription method dropdown
- Wait for model loading - you'll see detailed progress as the ~39MB model downloads and initializes
- Test with both file uploads and recordings - the same interface works with both input methods
- Verify offline functionality - once loaded, disable your internet connection and confirm transcription still works
The browser-based implementation provides several advantages for specific use cases. Privacy-sensitive applications benefit from keeping audio data entirely on the user's device. Offline environments can use transcription without internet connectivity. High-volume applications avoid per-request API costs after the initial model download.
However, there are important performance considerations to keep in mind. Browser-based inference is significantly slower than server-based processing, especially on lower-powered devices. The model download represents a substantial initial overhead that may not be justified for occasional use. Additionally, accuracy may be lower than the full-size models available through the OpenAI API, particularly for audio with background noise or non-common accents.
Running Whisper with Node.js
Server-side Whisper implementation offers significant advantages over browser-based solutions, particularly in performance and scalability. Node.js can leverage powerful server hardware, including GPUs, to accelerate model inference, resulting in substantially faster processing times compared to browser-based WebAssembly implementations. While this approach sacrifices the complete offline functionality of browser-based solutions, it maintains data privacy by keeping audio processing within your controlled infrastructure without relying on third-party services.
This section demonstrates how to integrate a self-hosted Whisper implementation using the nodejs-whisper package, which provides Node.js bindings for OpenAI's Whisper model optimized for CPU processing. First, install the nodejs-whisper package, which handles model loading, audio preprocessing, and transcription:
The package automatically handles complex tasks including model management, audio format conversion to the required 16kHz WAV format, and memory-efficient processing. However, it requires [FFmpeg] for audio preprocessing. Install FFmpeg according to your operating system requirements:
The transcriberFactory function implements the factory to create appropriate transcriber instances based on the service type. This approach provides several benefits: it centralizes transcription service instantiation, enables easy addition of new services without modifying existing code, and allows runtime selection of transcription providers through query parameters.
When the OpenAI transcription service is extracted, we can simplify our main src/server/index.js file to utilize the new transcriber architecture.
This update makes your server endpoint service-agnostic, allowing you to switch transcription providers by changing a query parameter. And finally, we can implement our WhisperTranscriber class and update the factory to support its initialization:
This allows us to use the WhisperTranscriber class through the same /api/transcribe endpoint by passing the transcriber=whisper query parameter. Test your new server-side Whisper implementation using curl:
The first request will take longer as the model downloads and initializes. Subsequent requests will process much faster. You should see output similar to:
You can pick different models by changing the modelName and autoDownloadModelName parameters in the nodewhisper function call. To see what Whisper models are available and their resource requirements, run:
The command outputs the list of models, their sizes and RAM requirements:
Choose models based on your available resources: use tiny.en for development and testing, base.en for balanced performance, or large-v3-turbo for production quality with reasonable resource usage.
Let's now integrate Node.js Whisper with our frontend application. Update your src/client/transcriber.js file to add a new NodeWhisperTranscriber class that extends the base OpenAITranscriber class:
The only differences between this class and the OpenAITranscriber class are the model name added as query parameter to the apiUrl. Additionally, we need to add a third option to the models selection dropdown in the src/client/index.html file:
And to make the frontend logic aware of the new WhisperTranscriber class, we need to update the src/client/index.js file:
This code initializes the WhisperTranscriber class when the user selects the "Whisper (Server)" option from the transcription method dropdown.
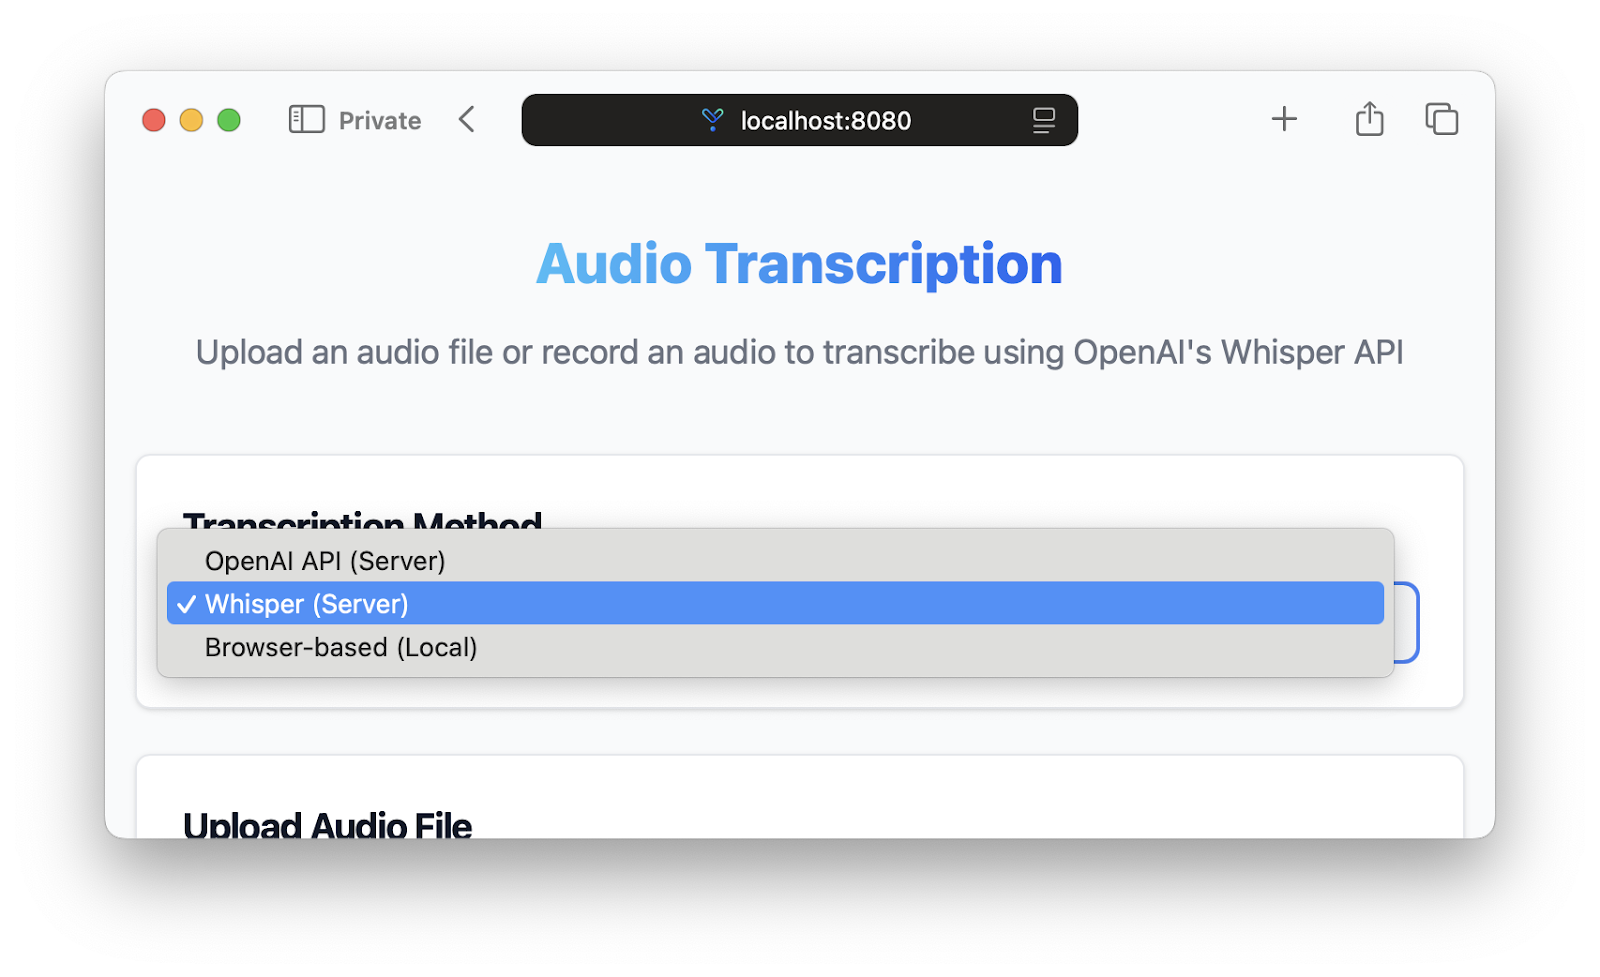
Navigate to http://localhost:8080 and test ensure the application now provides a flexibility to choose the three transcription methods: OpenAI API (Server), Whisper (Server) and Browser-based (Local).
Suggested Reads
- How to Build a JavaScript Audio Transcript Application
- Node.js Speech-to-Text with Punctuation, Casing, and Formatting
- Transcribe and generate subtitles for YouTube videos with Node.js
- Transcribe an audio file with Universal-1 in Node.js
- Summarize audio with LLMs in Node.js
- How To Convert Voice To Text Using JavaScript
- Filter profanity from audio files using Node.js
Experience real-time streaming, speaker diarization, and unlimited file sizes with AssemblyAI's Speech-to-Text API.